One frame from a four-gigabyte video
How a tiny ffmpeg service behind an edge worker turned 'a thumbnail at any timestamp of any video' from a years-old wish into a two-second URL, and what a suddenly-free capability does to a product conversation.
A video, any timestamp, 640 pixels wide: one customer’s home video, thirty minutes in. Click and a JPEG of that moment comes back in about two seconds, minted on demand from a multi-gigabyte file. The link carries an expiring signature; in an hour it’s dead. A founder who has wanted this capability for years, and had quietly filed it under impossible, replied with the exploding-head emoji. Then the ideas started, and they haven’t stopped.
#The problem that kept not getting solved
I run engineering at a consumer product that helps families preserve their memories. Behind it sits an archive of home video that is nothing like web video: the files run to gigabytes each, the recordings run to hours, and there are millions of them in private object storage. The longest one I’ve tested runs 4.8 GB and six hours forty minutes of somebody’s life.
Half the product ideas on our wall need the same primitive: a picture from a specific instant inside one of those videos. A clip needs a cover image. A “moments” email wants the frame where the birthday cake shows up. A scrubber wants a preview under your thumb as you drag. And for years, every route to that primitive failed the same audit:
- Pre-render everything. Thumbnails for every second of every video means billions of images, almost none of which anyone would ever look at.
- Cut frames on demand, the naive way. Download a 4 GB file to produce a 30 KB image — a hundred-thousand-to-one ratio of bytes read to bytes served, and tens of seconds per thumbnail.
- Buy it. Cloudflare sells frame extraction off the shelf, but it caps input at 100 MB and ten minutes 1 — our median video blows past both. A hosted media-transformation service we piloted earlier this year could handle the files, but it never beat the two seconds you just saw, and it priced the job in the thousands of dollars a month.
So the feature sat in the someday pile, looking like a big-company problem that wanted a big-company system.
#Three facts about files
Video files carry a map. An MP4 — what our masters are — contains an index, the moov atom, recording where every moment of the video lives in the file, down to the byte. 2 Read the index and you know which slice of a 4 GB file holds minute 133.
Video is keyframes plus diffs. Every so often — a second or a few, depending on the encode — the file stores a complete picture; the frames between only describe what changed. To render any instant, you jump to the nearest keyframe before it and decode forward a fraction of a second.
Storage speaks byte ranges. HTTP has let clients request an arbitrary slice of a file since the nineties. 3 Nothing obliges you to read the four gigabytes you don’t need.
ffmpeg composes all three when you pass the seek before the input — -ss ahead of -i — which tells it to consult the index and jump, rather than read the file front to back. Pointed at a signed storage URL, it fetches the index, does the math, range-reads the few megabytes around the target keyframe, and emits one JPEG.
A single master file is laid out as a small header, gigabytes of video data made of keyframes and diffs, and an index which in our files sits at the tail. ffmpeg, seeking to two hours thirteen minutes, makes three moves: first it reads the index, second it range-reads a few megabytes of video data around the target keyframe, and third it emits one 30-kilobyte JPEG.
A four-gigabyte video costs about as much to read as a large photo, if you know exactly where to look.
I measured it on the worst file we have, the 4.8 GB six-hour-forty tape: 1.9 to 3.0 seconds per frame, end to end, including the network — against a warm container; the first request after an idle spell pays a couple of seconds more while it wakes. And that’s with our current masters storing the index at the tail of the file, which costs an extra round trip to the tail before the seek can start. New encodes will write the index up front — one flag at transcode time 4 — and the same request should land well under a second. The encode pipeline, it turns out, is part of the feature: index placement, steady keyframe spacing, and a modest bitrate are what keep a frame read photo-sized.
#The service is boring on purpose
The whole thing is one small service and one route. An edge worker is the single front door for all customer media; every URL it honors is signed and expiring. Frame requests go to a scale-to-zero container running pinned ffmpeg, which holds a read-only storage credential and answers only to the worker. Extracted frames cache at the edge — the worker verifies the signature, then drops it from the cache key and snaps timestamps to the whole second, so two people asking for the same moment share one extraction and the second look is instant. No database, no queue, no pre-processing job crawling the archive. When nobody asks for frames, it costs nothing; when everybody does, the edge cache answers most of them, and the compute bill stays in single-digit dollars a month even at millions of requests.
A signed link carrying a timestamp and width arrives at the edge worker, which verifies the signature and checks its cache. A moment it has seen before returns a JPEG instantly. A first look goes to the frame service, a container running pinned ffmpeg with a read-only credential, which range-reads a few megabytes from private object storage and returns the JPEG in about two seconds.
None of that is clever, and that’s the point. The cleverness budget went into finding the facts, not into architecture.
#at=auto mode
at=auto solves a real UX problem: picking the right timestamp is hard, and most videos don’t have a single obvious frame. The service samples the opening 15 seconds at 2 frames per second, runs signalstats to detect blue screens (ULOW Cb) and near-black frames (YHIGH luma), rejects dead frames, and picks a representative thumbnail from the survivors.
The rejection thresholds come from calibrating on real tapes. Saturated leaders run ULOW ~217, VCR OSD blue screens run ~166-167, and real content tops around 114. We run at 160, so the service drops uniformly blue frames while keeping content.
Near-black detection uses YHIGH — the 90th-percentile luma — to catch dead-signal black frames. 5 The threshold is 32 (TV black 16 plus analog noise headroom). Real content runs YHIGH 110-214, so the filter drops only dead frames.
If the opening window exhausts, it seeks once to mid-tape and retries against a three-second window. If that also fails, the service returns a precondition-failed error with a machine-readable reason, and the caller shows a placeholder.
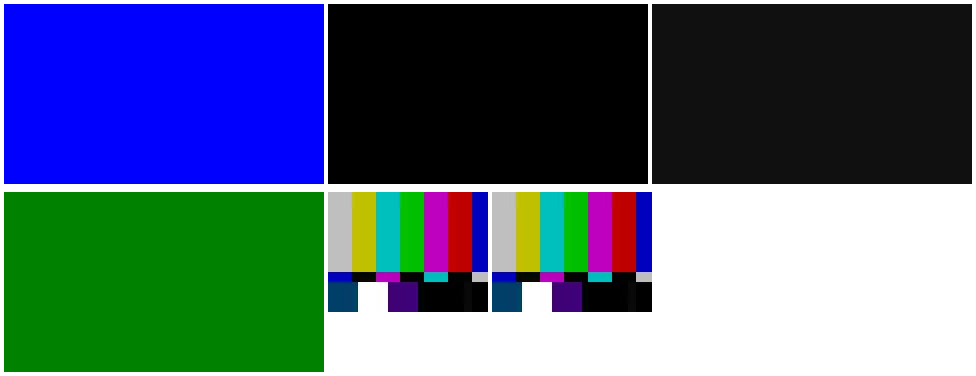
The service samples the opening 15 seconds at 2 frames per second, runs signalstats to detect blue screens (ULOW Cb) and near-black frames (YHIGH luma), rejects dead frames, and picks a representative thumbnail from the survivors. If both windows exhaust, it returns 412 PRECONDITION_FAILED and the caller shows a placeholder.
One ffmpeg pass does extraction and rejection simultaneously. The service returns a representative thumbnail in the same round-trip as a manual timecode.
#What it unlocked
The Slack thread after that link was the best part. Within hours the ideas moved past cover images and scrubber previews: grab ten frames from a video, let a model pick the most interesting one — a face, say — and make that the cover. Then the bigger question: how many frames do you actually need to understand what’s in an hour of home video? One per second is 3,600 images; one per ten seconds is 360, and probably closer to enough. Suddenly we’re sketching AI analysis of the whole archive as a bounded, priceable batch job, because sampling a video no longer means reading it. Extraction is no longer the expensive part; the model calls are.
Encoders that place keyframes at scene cuts have even left hints about where to sample — the file already marks the moments where the picture changes. Every idea in that thread used to open with “well, first we’d have to read the whole video,” and die there. The primitive changed price, and the conversation changed shape the same afternoon.
The someday pile is mostly problems priced under an old assumption. The assumption here was that video is opaque — that you get frames out of it the way you got them out of a VHS deck, by rolling through. The file format has disagreed since before some of our customers’ tapes were recorded. What’s left is this: write the index to the front of every new encode, and two seconds becomes half of one.
Notes
- Cloudflare Media Transformations input limits at the time of writing: 100 MB and 10 minutes per source video. Excellent for web-native clips; a non-starter for multi-hour home video. ↩
- The moov atom is the index box of the ISO Base Media File Format (ISO/IEC 14496-12), the container family MP4 belongs to. It maps every sample in the file to a byte offset, which is what makes timestamp-addressable reads possible at all. ↩
- HTTP range requests date to HTTP/1.1 (1997) and are specified today in RFC 9110. ffmpeg's input seeking (
-ssbefore-i) is what turns a seek into ranged reads instead of a sequential scan. ↩ - The
-movflags +faststartoutput flag relocates the moov atom to the front of the file, written for progressive web playback in the dial-up era and still earning its keep. Per file it's a cheap stream-copy remux, no re-encode -- though across an archive like ours that still means rewriting every byte you own, which is why we're fixing it at the encoder for new files rather than backfilling. The measured tail-seek penalty on existing files is small enough to live with. ↩ - We use 90th-percentile YHIGH instead of mean luma because a dim ~15% strip would be wrongly dropped by mean. The 90th-percentile rule catches the signal floor while preserving content that has a bright foreground against a dark background. ↩